Be Creative. Don't Invent.
An AI agent helping with site reliability engineering (SRE)—keeping services available—can search broadly during an incident without inventing facts. In one investigation, the alert was real, but the agent supplied a rule identifier that did not exist, a metric family that was not collected, and a lead drawn from exporter warnings when it could not reproduce the reported symptom. Those details made the resulting explanation look stronger than the tool results allowed.
The useful distinction is between changing how you search and filling a missing result with a plausible-sounding value.
Search beyond the first failed query
| Creative (The Goal) | Invent (The Bug) |
|---|---|
| Retry the identifier copied directly from the alert page | Create an unverified identifier from the title |
| Discover available measurement series after an empty PromQL query | Guess a counter from an unrelated, past incident |
| Broaden label filters using values in the alert or returned data | Paste tokens from an entirely unrelated playbook |
| Treat exporter warnings as a possible collection problem, not proof of the incident cause | Promote them to “Theory” because something had to be wrong |
| Close with undetermined and suggest next probes | Close with a tidy, fabricated mechanism you never reproduced |
A defensible search can widen from identifiers in the alert, retrieved documentation, or tool results. Retrieval-augmented generation (RAG) means supplying retrieved documents to the model as context; those documents still need to be checked for relevance. Invention begins when a value is guessed because it resembles a value from another incident.
We saw two versions of the shortcut: guessed failure counters after a PromQL (Prometheus query language) search returned No data, and guessed alert details after loading the alert rule failed. Neither empty response establishes that a guessed value exists.
Why instructions alone are insufficient
A large language model (LLM) can still fill gaps under uncertainty despite an instruction not to guess. A root-cause analysis (RCA) should therefore link names and measurements to their sources.
Adding another FORBIDDEN paragraph to a system prompt did not address these cases. A more testable control is to validate important identifiers and query inputs against the alert or recorded tool output before using them in a conclusion.
The proposed boundary applies at specific decision points: metric identifiers, queries, control-plane status (the systems managing infrastructure), terms used to broaden log searches, and the conclusion when a symptom cannot be reproduced. This narrows what can be checked mechanically; it does not guarantee the remaining interpretation is right.
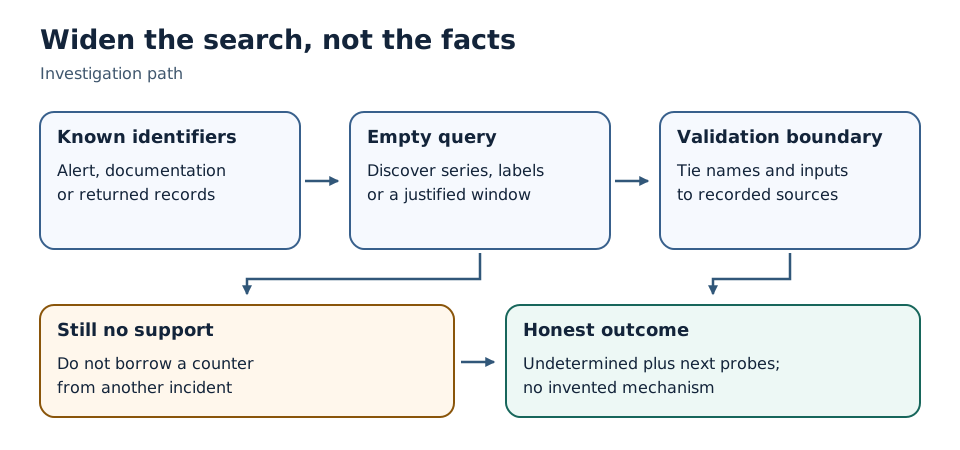
Diagram: The arrows broaden a search only from sourced identifiers, then validate query inputs before synthesis; the lower path keeps a failed search unresolved rather than filling the gap with a guessed metric or mechanism.
An unresolved result with next checks is more useful than a fabricated cause.
An unresolved finding with named next checks gives responders something to evaluate. A fabricated identifier, by contrast, can waste time in an active incident. Recorded monitoring data is a stronger basis for a claim than plausible prose, though it too can be incomplete.
Related
Does your AI agent dig harder when stuck in incident response — or invent the missing piece? Find me on GitHub or LinkedIn.
StackGen is building AI-assisted incident triage. Our offering aims to help teams run diagnostics and draft RCA reports; operators should still verify consequential findings. See ai.stackgen.com.
Stay in the loop — production notes on AI agents, workflows, and SRE.
Low volume — new posts and curated reading lists. Unsubscribe anytime.